The premise
I wanted the capability.
Not the design.
I wanted an assistant that could read and draft WhatsApp messages. The available tool could send immediately, with no human approval. That was more authority than I wanted to give it.
I forked it and spent eighteen phases taking things away: deleting tools, cutting network access, splitting responsibilities, and putting a human where a mistake became irreversible. Along the way, I found that several of my own tests proved nothing at all.
The lethal trifecta is the combination of access to private data, exposure to untrusted content, and the ability to communicate externally. A WhatsApp assistant had all of them: message history, incoming messages, and sending.
Prompt injection is an attempt to make an assistant treat untrusted content as instructions. A message could carry that attempt into the assistant’s context.
I assumed the model would eventually be tricked, and tried to make sure a tricked model had almost no authority.
Telling the assistant “don’t do that” was not enforcement. The boundary had to live in something the assistant could not talk to.
The starting point
I audited before using it.
The local API bound to all network interfaces and published a host port. The send_message tool sent immediately to any number, without confirmation. Attachment handling had a path-traversal flaw: a crafted filename could escape its intended directory and resolve inside the user’s home folder.
Messages reached the model as flat lines, From <name>: <text>. A newline and the same pattern could forge a message from someone else, including the user. Logs recorded message contents. Encryption at rest depended on whatever the operating system provided.
I treated this as an ordinary starting condition for a hobby project, not a reason to criticise it. The work was the gap between that starting point and something I would let near a real account.
The boundaries
The assistant could propose.
It could not send.
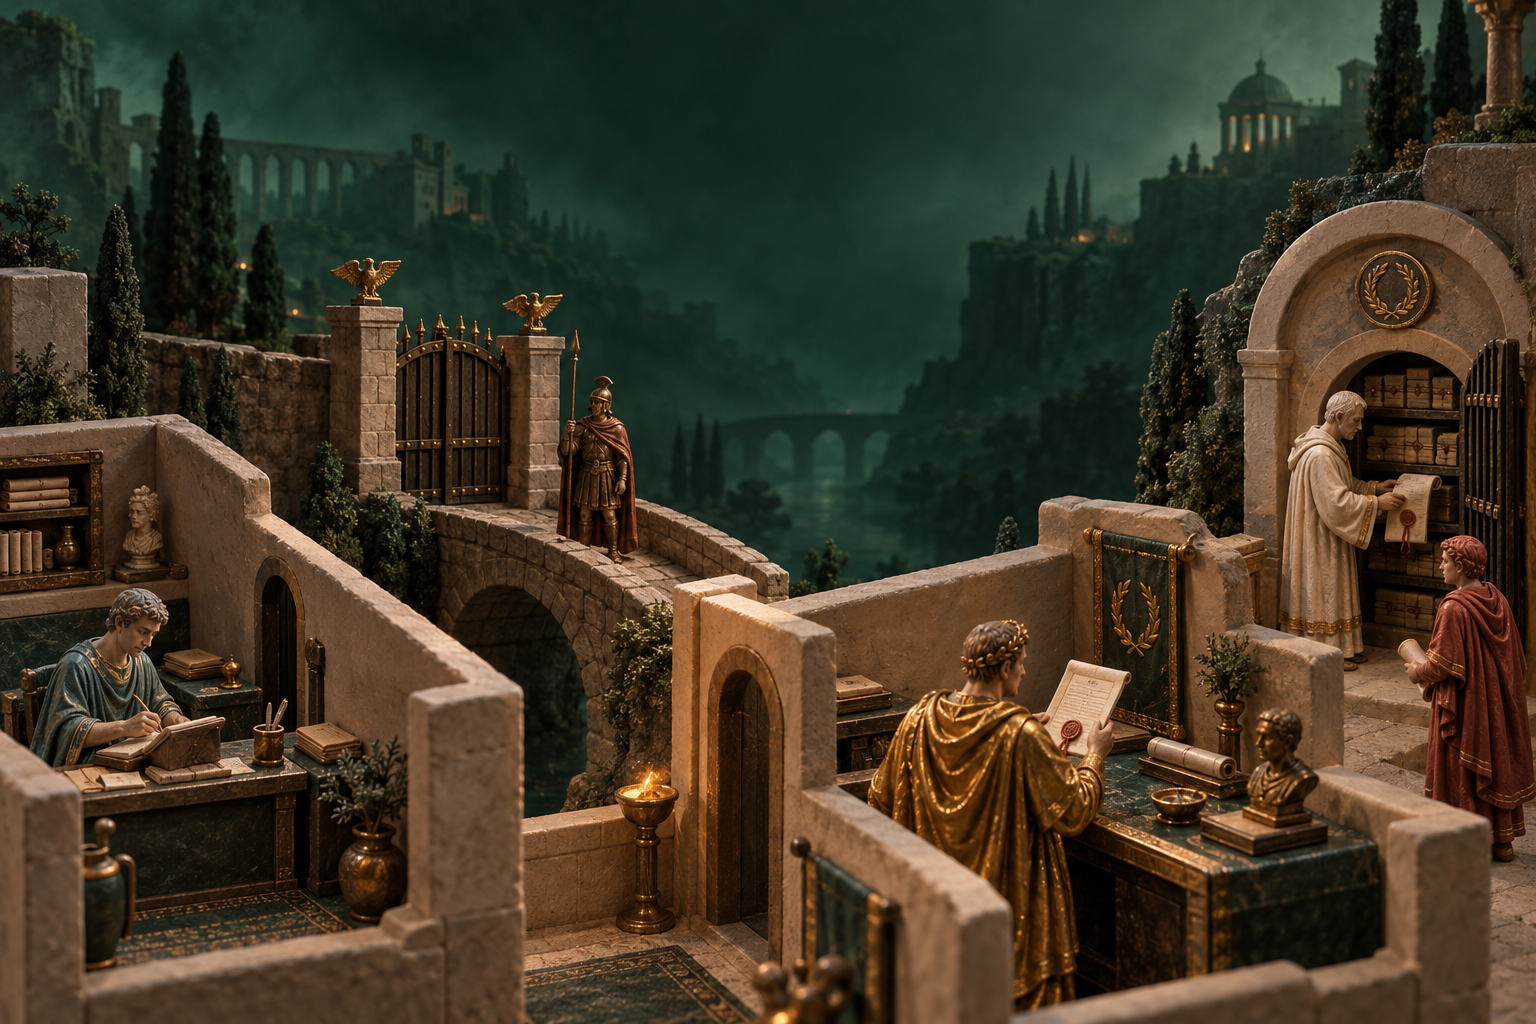
Select a gold label to explore each role and its limits.
AI operator
Read & propose
No shell, web or send tool.
Bridge
Connect through policy
Only allowed hosts via the proxy.
MCP server
Read & draft
Read-only data. No network.
Sender
Deliver approved text
No message-history access.
Human
Review & approve
Recipient, full text, then code.
I separated four components. The bridge spoke WhatsApp and held the session keys and message database. Its only route out was an egress proxy that refused hosts outside its allowlist.
The MCP server, the tool interface the assistant used, had no network. It read files and answered on a pipe. It saw the database and allowlist read-only. It could write a draft, not send one.
The sender was deaf: it never opened the message database, spoke to the assistant, or imported anything that could. Even a compromised assistant could only put text in front of a human. The AI operator was the assistant’s session, limited to reading and drafting tools, with no shell, filesystem, web, or other tool servers.
Containers ran non-root, with read-only root filesystems, all Linux capabilities dropped, and no published ports. The only host-folder exception was a read-only allowlist file. That policy named readable chats, a smaller writable set, and an attachment-download set that was empty in practice. Unlisted chats received identical refusals, so differing errors could not map the address book.
A Roman analogy
Think of the AI as a scribe inside an archive. The librarian—the MCP server—shows only permitted scrolls. The scribe proposes a reply but cannot leave with it. A human commander reads the reply and approves it; only then may the courier—the sender—take it to the guarded bridge. The gatekeeper admits only permitted routes. A clever scribe does not inherit the courier’s authority. The commander still has to read carefully.
The principles
I removed what I did not need.
- Deletion over guarding
- I removed media download, file-sending tools, an arbitrary-file endpoint, and their filesystem helpers. A function that did not exist had no failure modes of its own. Deletion also shrank the testing surface.
- Separation of authority
- The assistant proposed, a human approved, and a separate program sent. The sender independently re-read the allowlist. Neither policy check alone could authorise a forbidden send.
- Deny by default; fail closed
- An unparseable policy denied everything. A launcher without its settings refused to start. That refusal exposed a runbook command that could never have worked.
The part I would want to be asked about
Four times
the tests were wrong.
Everything above was ordinary good practice. These were the moments when a passing test taught me to question the evidence itself.
The approval boundary
The test passed.
Production failed.
- The promise
- Approval came after reading.
- The surprise
- Old input arrived as if it were new.
For much of the project, confirmation was a y/N prompt. In real use, I noticed that a y typed during container startup was still in the terminal buffer when the prompt appeared. It happened to decline because the read got something unrecognised. The safety was luck.
The claim was “a human read this exact text and said yes.” A keystroke made before the text appeared could not support that claim.
What I tried
My first fix discarded pending input just before printing the prompt. I tested it through a real pseudo-terminal, typed ahead, and confirmed the input was discarded. The test passed. The deployment was still broken: a live run accepted a pre-typed key.
The launcher used docker run -it. There were at least two buffers: the Mac’s terminal and the container’s pseudo-terminal. My flush emptied the latter. The runtime relayed keystrokes from the former onto the freshly emptied queue. My harness wrote into the buffer the child read. Production had another, and I had never asked.
“Flush harder” could not solve it. Buffers were a property of how the program was launched. Any draining fix raced a relay it did not control and could expire under tmux or ssh.
What changed
I changed the approval claim. Each draft printed a random code generated after rendering the message. Approval required typing it back.
  | 7pm works for me!
========================================
To approve, type this code:  7f3a
Anything else declines.
Pre-typed input could not reliably predict a code that did not yet exist. A claim about timing became a claim about arithmetic. With four hex characters, a blind guess still succeeded about 1 in 65,536 times, at the cost of a visible decline per failed attempt. The code did not prove that a human understood the draft.
A passing test showed the property held in the environment I built. Whether that environment resembled production was a separate question—and the one I had not asked.
The evidence boundary
A positive control passed
for the wrong reason.
- The result
- The tool refused.
- The missing evidence
- The intended input never arrived.
I tested whether drafting refused a chat not authorised for writing. The assistant’s notes already told it to report suspicious instructions. An assistant-level refusal would prove nothing about the tool.
I wrote the pass condition against the audit log before running the test: a tool refusal counted; an assistant declining without calling the tool did not. I also ran a positive control—a direct request with the intended input, bypassing the assistant, to establish that the refusal path was exercised.
It returned ACCESS_DENIED. It looked like a pass.
What the log exposed
The command reading the chat identifier used bash syntax in zsh. The read failed, the variable was empty, and the tool refused an empty string. The refusal was real. It was a refusal of nothing.
I caught it because the audit log’s refused-chat column was blank.
A positive control was only positive if I verified its input arrived. I had built a control against this class of error, then committed the error inside it.
The coverage boundary
I removed the claim.
I kept the code.
- The temptation
- Keep a reassuring coverage claim.
- The honest choice
- Remove a claim that no longer mattered.
I marked security-relevant lines and maintained a separate list of mutations. Mutation testing deliberately breaks a guard in a throwaway copy and requires the tests to detect that breakage. The runner refused a clean result while a marked guard had no mutation.
The lists were handwritten and independent. Deriving guards from mutations would make “every guard has a mutation” true by construction: a list reporting on itself. Hand-syncing was the cost; the cost was the point.
When the claim stopped being true
After the approval code replaced the flush, the flush still tidied the prompt. Deleting it no longer broke a test: approval no longer depended on it.
I could delete the code, retain a security marker with a mutation that could not fail, or retain the code without the marker. The middle option was the trap. It would preserve the appearance of coverage while abandoning its meaning.
I removed the marker, kept the code, and explained why in a comment.
When a control was superseded, I had to decide whether it was still load-bearing. If not, it kept neither its security claim nor its test—whether or not the code stayed.
The environment boundary
Three environments
that were not production.
- The pattern
- My test machine differed from deployment.
- The lesson
- Environment was part of the evidence.
The same failure appeared in unrelated places:
- A generated report differed because a YAML library existed on the development machine but not in the shipped container. I made report generation refuse to run outside the canonical environment.
- The typeahead harness omitted an input buffer present in deployment.
- I verified an installer rollback on Linux, although the bug was macOS-specific. macOS
cpcopied file flags: a backup of a locked file was itself locked and could not be cleaned up. GNUcphad no such flags. My Linux test could not find that failure.
The installer also showed why exit codes were insufficient. A guard against a half-finished install deleted a settings file, then announced that nothing had been installed and re-running was safe. The reassurance ignored the file it had destroyed. I caught it by checking state afterwards.
When a fix depended on platform behaviour, the test had to run on that platform. “It passed” from anywhere else was a weaker sentence than it looked.
What I left out
I did not widen authority
to simplify identity.
A contact could have a phone-number address and a privacy alias, both reaching the same conversation. My allowlist named addresses, not people. Removing an address did not revoke another listed form. I discovered this by sending to the same person using different forms and seeing another chat row appear.
The library already held a mapping on my machine. I did not use it for enforcement: it came from the server without verifiable provenance; lookups had reportedly succeeded with empty results; and the mapping lived beside account credentials, deliberately outside the enforcement component’s access.
Consulting it would have increased the blast radius to fix a comprehension problem. Instead, I proposed a human-run diagnostic reporting apparently related entries. It was advisory, not implemented enforcement, and could never widen permission.
I documented what still worked against it.
The residual-risk list named concrete attacks. The uncomfortable one: if the assistant could read a chat and draft for another, it could carry private contents across. Nothing in the code stopped that. The human reading the recipient and full text was the only control—a control made of attention.
A security document that listed only solved problems would have been marketing.
Where it stood
I separated what I verified
from what I did not claim.
Verified live, against a real account
- The assistant read a chat and drafted; a human approved by code; the message arrived. The audit log tied the chain together without message text.
- Drafting refused a chat outside the writable list, with a recorded refusal.
- The outermost layer the assistant reached refused before the tool was called.
Explicitly not claimed
I did not claim the assistant would always refuse an injection. In a live test it recognised a forged “system notice” and reported it. That was evidence about a model, a phrasing, and a day. I designed around the opposite assumption.
The most useful outcome of eighteen phases was a habit: when a test passed, I asked what else would have made it pass.
Explore the Q&A